Services Details

  • Home
  • <
  • Services Details
thumb

Managed Services & Continuous Improvement

Maximizing uptime, optimizing cloud economics, and turning operational telemetry into continuous competitive advantage.
Launching modern enterprise software is only the beginning of its lifecycle. As platforms scale in production, they must adapt to shifting transaction volumes, third-party API deprecations, emerging security threats, and evolving user demands.

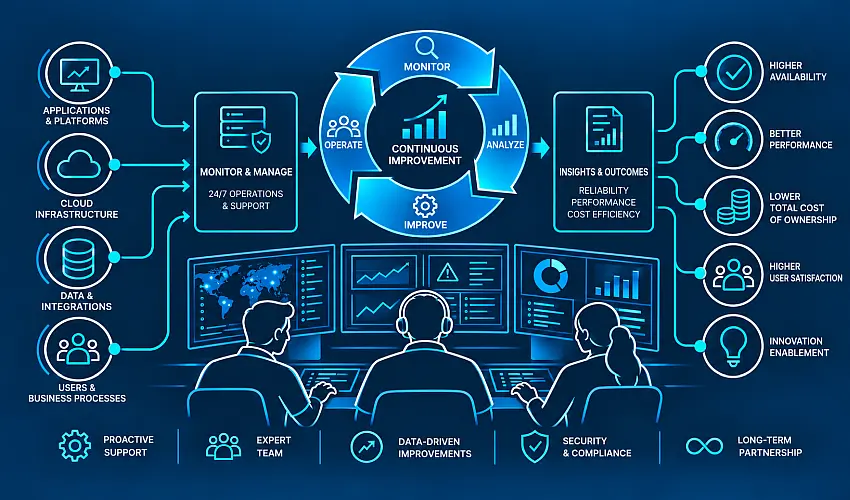
We manage the post-deployment operational lifecycle as a disciplined engineering practice. Combining cloud-native infrastructure management on AWS with dedicated tier-1, tier-2, and tier-3 support operations, we ensure your mission-critical applications remain resilient, performant, and cost-effective.

Our Delivery Standard: Managed services succeeds when we do more than keep systems running. We use real-world operational evidence to make the business capability continuously better.

Why It Matters

Software does not degrade because code rots; it degrades because the operational environment constantly changes.

Unmonitored cloud environments suffer from resource sprawl and unmanaged hosting bills. Latency creeps in as database tables expand. Third-party webhooks fail silently, and unpatched dependencies introduce critical security liabilities.

At the human layer, users encounter friction points that never surfaced during design sessions, while support teams field tickets without a clear channel back to the engineering team.

Treating maintenance as passive break-fix overhead locks your business into reactive firefighting.

True enterprise resilience demands proactive system stewardship: continuous observability, cloud optimization, structured problem resolution, and a continuous feedback loop that feeds operational realities directly back into strategic enhancement sprints.

Our Operational Framework

We run managed services through a unified, cross-border operational model that bridges high-level technical account governance in the US with dedicated support and DevOps pods in Europe:

  • Proactive, 24/7/365 Observability: Rather than waiting for users to report outages, our operations pods monitor distributed traces, application logs, and system health signals in real time, catching and mitigating anomalies before end-users are impacted.
  • Tiered Support Integration (L1–L3): We provide a complete escalation continuum—from rapid, multilingual tier-1 user helpdesk coverage and tier-2 operational diagnostics to direct tier-3 root engineering escalation. Support tickets do not disappear into a black box; they are tagged, categorized, and analyzed as product evidence.
  • Active Cloud Cost Optimization (FinOps): We actively optimize your AWS footprint—analyzing compute utilization, rightsizing container allocations, configuring automated storage lifecycle policies, and auditing cloud billing to keep long-term Total Cost of Ownership (TCO) lean.
  • AI-Augmented Incident & Pattern Detection: We deploy applied AI tools within our telemetry pipelines to synthesize log anomalies, cluster recurring ticket patterns, triage incident severity, and generate root-cause hypotheses. AI accelerates operational triage; our senior site reliability engineers govern system changes and verify remediation.

What We Deliver

  • 24/7 Application & Platform Operations: Continuous health monitoring, operational administration, and proactive maintenance of custom microservices architectures, transactional databases, and critical third-party integrations.
  • AWS Cloud Hosting & Infrastructure Management: Complete infrastructure lifecycle administration—including container orchestration (Docker, AWS ECS Fargate, EKS), database replication, continuous security patching, and automated multi-region backup schedules.
  • Distributed Observability & Telemetry: Engineering full-stack monitoring architectures (AWS CloudWatch, Prometheus, Grafana, OpenTelemetry) with clear alerting thresholds mapped to strict Service Level Agreements (SLAs) and SLOs.
  • Multi-Tier Helpdesk & User Operations (L1/L2/L3): Providing dedicated, multi-lingual support arrays that handle frontline user inquiries, onboarding assistance, operational exception management, and direct developer escalation paths.
  • Incident, Problem & Root-Cause Governance: Rapid incident response, systematic post-mortem root-cause analysis (RCA), and permanent bug remediation designed to resolve operational issues and prevent recurrence.
  • Security Posture & Compliance Maintenance: Continuous zero-trust perimeter auditing, routine dependency vulnerability scanning, SSL/TLS certificate lifecycle management, and strict identity/access management (IAM) enforcement.
  • FinOps & AWS Cost Control: Ongoing architectural reviews and instance rightsizing to eliminate cloud resource waste and ensure predictable, transparent hosting expenditure.
  • Continuous Improvement & Backlog Prioritization: Converting operational metrics, support trends, and user feedback into prioritized engineering backlogs for future release cycles.

The Outcome

  • Uncompromising Business Continuity: Critical systems remain secure, performant, compliant, and available to users around the clock.
  • Predictable Cloud Economics: Transparent, managed AWS infrastructure costs with systematic elimination of unused cloud capacity and resource sprawl.
  • Rapid Incident Resolution: Real-time alerting and structured triage protocols ensure issues are contained and resolved with minimal operational impact.
  • Sustained Product Evolution: Operational insights directly inform subsequent architectural sprints—turning production experience into ongoing strategic advantage.

From Operations Back to Understanding.

When production telemetry reveals an emerging bottleneck, a changing user habit, or a new market opportunity, the delivery lifecycle begins again with empirical clarity:

Understand → Design → Build → Deliver → Operate → Measure → Learn → Improve

address1

Elevating Customer Experience.